
Explore the conversation.
Mainstreaming high-throughput biodiversity monitoring using AI
AI identification platforms like ARISE can take sensor data automatically to GBIF-published, standardised data for protected-area managers, but training costs are high and human verification still matters.
Niels Raes ↗
Delivering AI for biodiversity data in the public sector: data handling, security and humans-in-the-loop when small teams build at pace
Small public-sector teams can use AI tools productively if they set clear boundaries between prototype, dev, test and production and keep expert humans in the loop.
Rachel Wiles ↗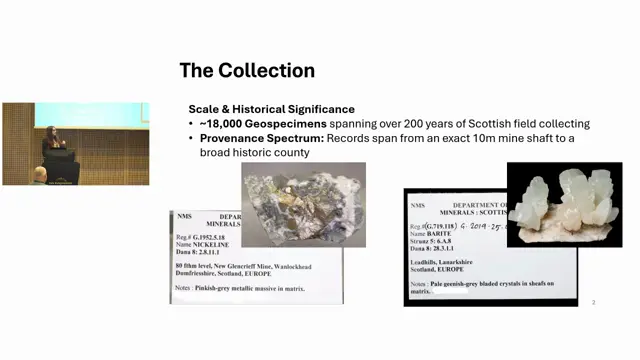
Improving geospecimen provenance and findability in the National Museums Scotland Scottish mineral collection
A scripted, reviewable workflow can quickly reconcile legacy mineral records and enrich them with Mindat coordinates, while giving data back to the community resource.
Sarah Stewart ↗
Trapper 2.0: scalable, open-source platform for managing camera trapping projects with integrated AI pipelines
Trapper 2.0 offers an open, model-agnostic, edge-deployable pipeline for camera trap photos and videos with expert review and Camtrap DP export.
Karolina Kuczkowska ↗
The WildLIVE Portal: Towards Scalable Wildlife Monitoring through the Integration of Citizen Science and Human-in-the-Loop AI Workflows
WildLIVE combines a model registry, provenance-tracked human verification and FAIR publication to move camera trap data from raw images to publishable data.
Rajapreethi Rajendran ↗
AI-assisted digitisation of printed identification keys: from book to structured data in minutes
An agentic LLM pipeline can turn printed keys and descriptions into a structured draft identification key for tens of dollars, shifting experts from transcribers to reviewers.
Wouter Koch ↗
The Swedish experience on verification and how to improve quality on observations
Human verification remains essential, and the community needs a standard to exchange verification status between systems.
Mora Aronsson ↗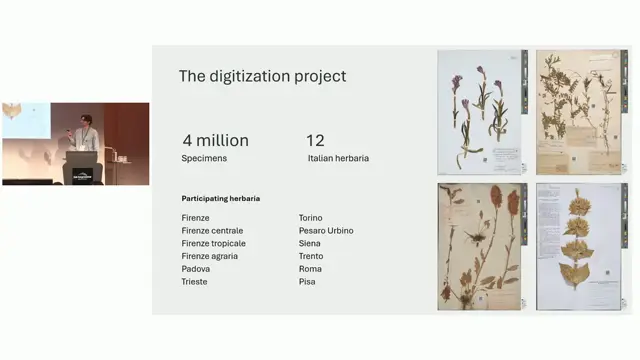
AI-assisted georeferencing a posteriori of herbarium specimens: a case study on Italian herbaria
Combining LLM parsing and LLM judging with gazetteers more than doubles correct georeferences for historical herbarium localities compared with Google Maps, even with a local model.
Matteo Conti ↗
How Darwin Core enables harmonizing Biodiversity Data via the OSCA Consortium
A shared Darwin Core-based cloud pipeline lets 15 Austrian institutions of very different IT capacity publish harmonised specimen data.
Cristian-Dan Bara ↗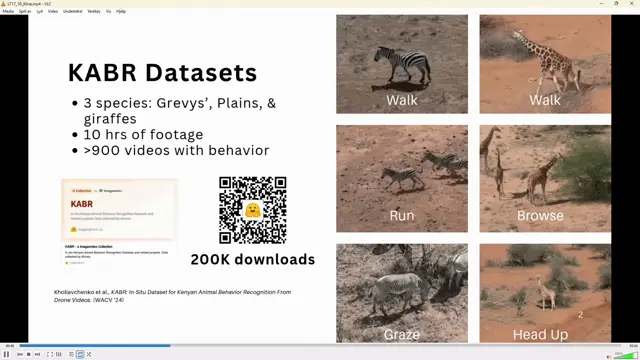
kabr-tools: A Modular Workflow for Automated Video-Based Behavioral Monitoring Across the Autonomy Spectrum
kabr-tools offers a modular, model-agnostic pipeline from drone or camera-trap video to ecological behaviour analysis.
Jenna Kline ↗
LT17 closing Q&A: AI hallucinations, validation and lightning-talk format
Validation of large-scale AI output remains open; for ML classifiers, accuracy should be judged on the ecological task rather than benchmark metrics.
Jack Hollister, Haris, Tanya Berger-Wolf ↗
Bridging the Gap: Strategies for Integrating Person Identifiers into Collection Databases
Wikidata's community-built person data can be used to pre-structure candidate matches, but expert judgement and institutional priorities remain essential for identifying collectors.
Frederik Berger ↗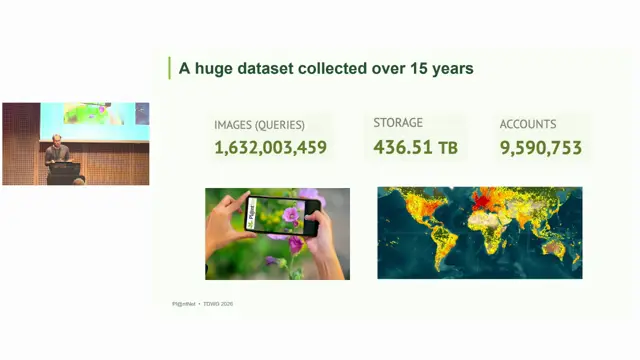
From 1.5 Billion Raw Queries to AI-Ready Biodiversity Data: Human-AI Collaborative Curation Pipelines in Pl@ntNet
Pl@ntNet's human–AI pipeline filters a vast, noisy stream into two GBIF datasets and training data, with separate branches for opted-in human-validated and automatic occurrence-only data.
Alexis Joly ↗
On-Device AI for Data Cleaning, Standardisation, and Exploration in Collections Management
Local LLM hardware can clean and enrich millions of legacy collection records at predictable cost, but validation of the outputs is the unsolved problem.
Jack Hollister, Unidentified co-presenter ↗
From Historical Oology Cards to Structured Biodiversity Data: Multimodal LLM Transcription, Uncertainty Metrics, and Human Review
Token-level hesitation from log-probabilities does not tell you which transcriptions are wrong, but it reliably predicts where human review effort will go.
Grete Pasch ↗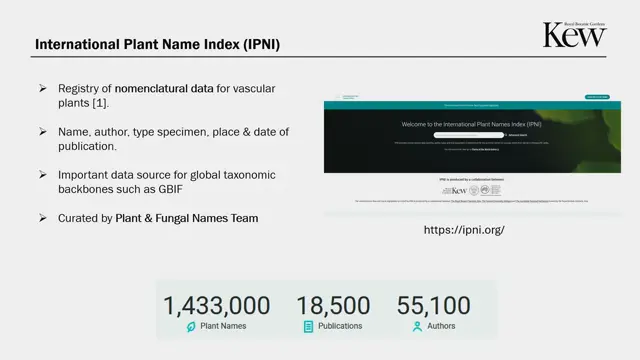
LLM-Based Pipeline for Extracting Nomenclatural Acts from Taxonomic Literature
A grounded, schema-constrained two-pass LLM pipeline extracts IPNI-ready nomenclatural data well once treatments are found; finding treatment boundaries is the bottleneck.
Ishaipiriyan Karunakularatnam ↗
Reliable LLM-assisted curation of ecological survey data: a deployed agent bridging field collection and data curation
An LLM agent that proposes findings for curator approval, with confirmed patterns turned into deterministic rules, catches plausibility errors that schema validation misses.
Andrew Tokmakoff ↗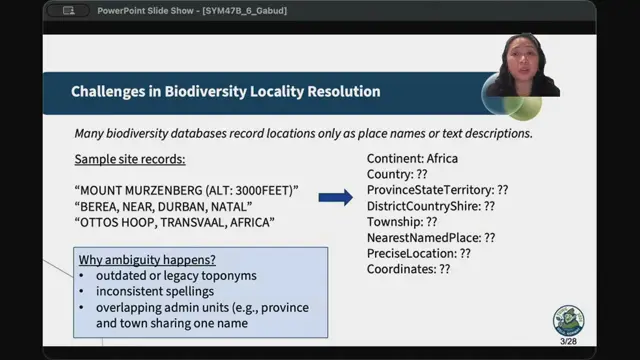
Enhancing Biodiversity Georeferencing Using Large Language Models and Knowledge Graphs
LLM preprocessing plus knowledge-base matching fills in locality hierarchies and proposes coordinates, with a review tool to keep humans in control.
Roselyn Gabud ↗