
Explore the conversation.
Delivering AI for biodiversity data in the public sector: data handling, security and humans-in-the-loop when small teams build at pace
Small public-sector teams can use AI tools productively if they set clear boundaries between prototype, dev, test and production and keep expert humans in the loop.
Rachel Wiles ↗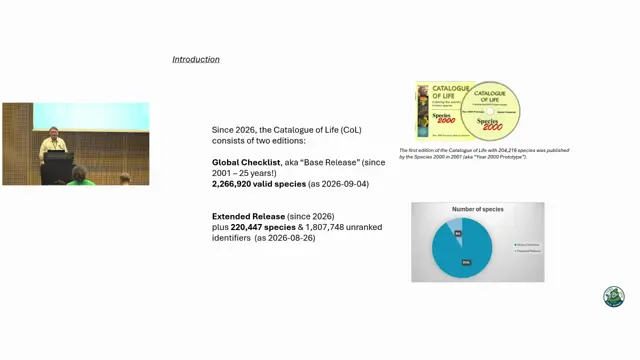
The United States contribution to the global taxonomy of the Catalogue of Life in the first quarter of the 21st century
US experts and platforms supply over a third of the Catalogue of Life, and the next step is an identifier-based infrastructure passing unchanged IDs between databases.
Yury Roskov ↗
Managing observations when taxonomy changes: the case of Artportalen and Dyntaxa
Concept-based taxon IDs with traceable history let a large observation system absorb taxonomic change pragmatically.
Johan Liljeblad ↗
Closing the Loop: The DiSSCo Annotation Validation Framework for Trustworthy Data Round-Tripping
DiSSCo proposes impact-based, layered validation so trusted annotations are promoted automatically and only high-impact ones need expert review.
Wouter Addink ↗
Transitivity Failures in Taxonomic Name Resolution: Implications for Botanical Dataset Construction
Always keep original verbatim names so datasets can be re-resolved against the latest taxonomy.
Adam Richard-Bollans ↗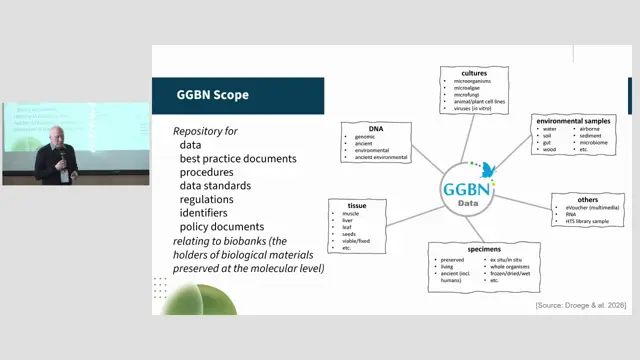
Rebuilding core functionalities of the GGBN system: taxonomic alignment with international research infrastructures
GGBN is rebuilding transparent automated name parsing and matching on GBIF parsing and ChecklistBank/Catalogue of Life XR to improve sample discovery.
Walter Berendsohn ↗
The BMD Cubing Engine: Harmonizing Biodiversity and Earth Observation Data
BMD's cubing engine turns a declarative YAML recipe into reproducible, provenance-documented data cubes that harmonise GBIF occurrences with climate and Earth observation data on one grid.
Mathias Dillen ↗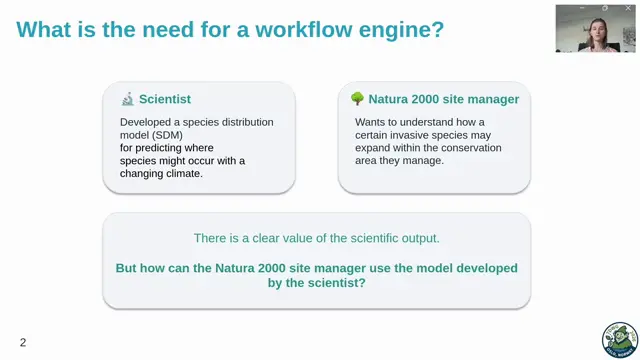
BMD workflow engine: FAIR workflows, RO-Crate and FAIR Signposting for a European biodiversity data space
Packaging containerised workflows and their runs as RO-Crates with FAIR Signposting lets non-technical users run models remotely and get machine-actionable, citable results.
Lena Perzlmaier ↗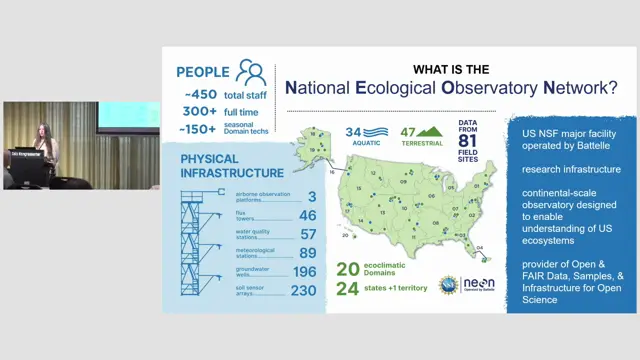
NEON, Community Standards, and the Hyper-Extended Specimen
NEON was built for interoperability from the start, but sustaining standards, crosswalks and value-added links needs community-level solutions.
Chandra Earl ↗
Confronting legacy data for primary type specimens
Decades of database migrations left the second-largest insect collection's type catalogue unreliable, and only a full physical inventory is fixing it.
Cailin Meyer ↗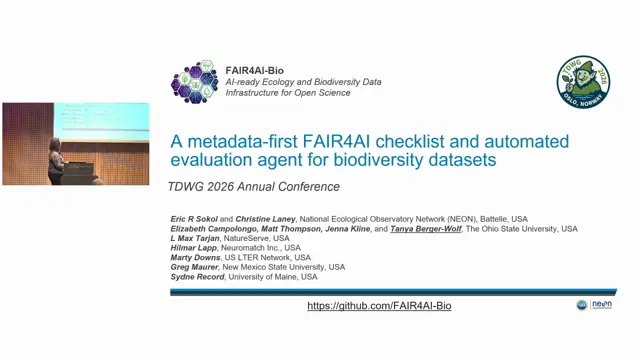
A metadata-first FAIR4AI checklist and automated evaluation agent for biodiversity datasets
FAIR4AI is mainly a metadata gap, and a community checklist plus an automated agent can measure and help close it while tracking provenance and governance back to data sources.
Tanya Berger-Wolf ↗
Phenobase: a harmonized, AI-ready knowledge base of global plant phenology
Combining ontologies with machine learning lets Phenobase close global phenology data gaps, but making the result AI-ready requires per-record model provenance, quality and citation.
Robert Guralnick ↗
Unifying Biodiversity Images: Content-Based Identification with the ISCC standard (ISO 24138:2024)
ISCC gives images a content-derived, similarity-comparable identifier that anyone can recompute, addressing duplication, broken links and AI-generated fakes.
Wouter Addink ↗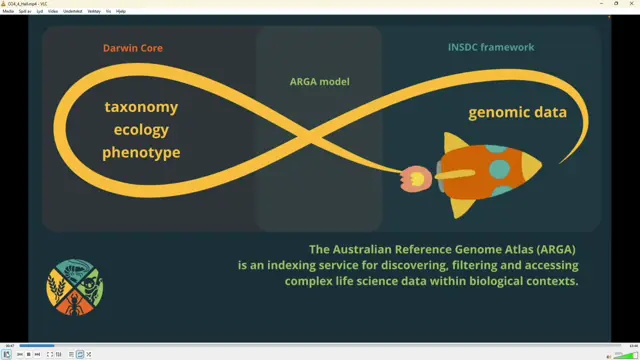
Visualising specimens as event chains on the Australian Reference Genome Atlas
Modelling genomic data as event chains from organism to data product preserves context and provenance that flat records collapse.
Kathryn Hall ↗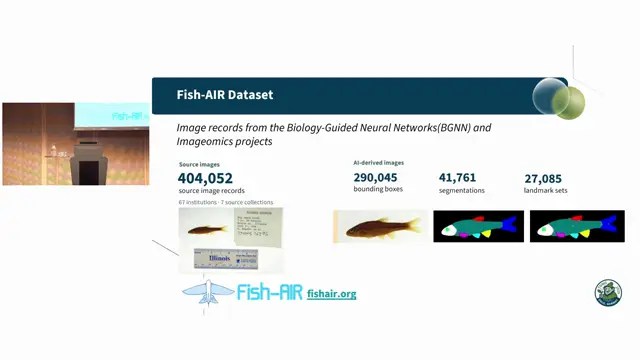
Provenance, Lineage, and Auditability in AI-Driven Biodiversity Image Workflows
Two persistent-identifier links per derived image, parent and batch, are enough to preserve auditable lineage and pipeline context for AI-processed biodiversity images, even outside the repository.
Xiaojun Wang ↗
The More Extended, The More Open: Semantic Integration of 3D Natural Heritage Data into Biodiversity CMS
Treating 3D specimen models as entry points in a knowledge graph that includes heritage context and digitisation paradata makes them reusable knowledge assets.
Yeeun Lee ↗
The Planetary Knowledge Base: an infinite solutions engine converting data into action for nature
The NHM is building the Planetary Knowledge Base in phases, with provenance, attribution and benefit-sharing designed in, to move biodiversity data to evidence to action at scale.
Vincent Smith ↗
Using Large Language Models to enhance biodiversity knowledge extraction: From taxonomic treatments to graph-based knowledge systems
Taxonomic treatments hold underused habitat knowledge that LLMs and a provenance-preserving knowledge graph can structure and link to ecoregions, helping map data-poor species.
Ian Ondo ↗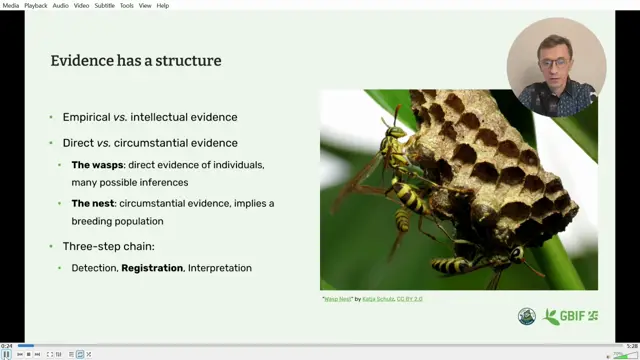
Handling evidence: a cross-disciplinary perspective
Biodiversity standards should stop treating what was recorded and what was concluded as the same kind of fact, borrowing evidence-handling practice from forensics, archaeology and medicine.
Dmitry Schigel ↗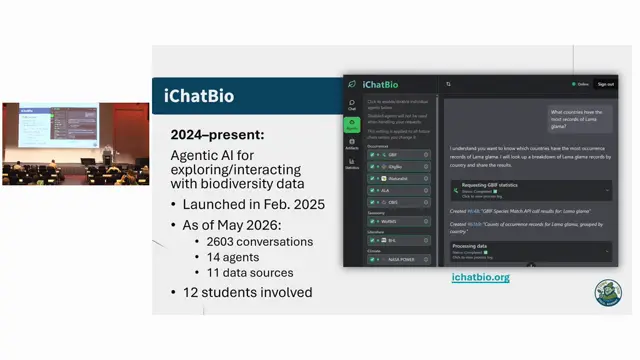
Integrating Many Data Sources in iChatBio Enables Emergent Scientific Use Cases
iChatBio's specialised agents let a conversational interface combine many biodiversity data sources, with traceable, non-hallucinated data artefacts.
Michael Elliott ↗