
Explore the conversation.
Open Digital Curation Needs: openness, interoperability, provenance
Open digital curation increases transparency, agency and trust and reduces latency, but needs new provenance practices for AI.
Deborah Paul ↗
Requirements of Sustainability Models for Geo-Biodiversity Data Cyberinfrastructure
Cyberinfrastructure sustainability and ecosystem sustainability go hand in hand, so infrastructure must be designed from the start to track use and support economic orchestration.
José Fortes ↗
Symposium discussion: funding models, open data and sustaining biodiversity infrastructure
The community broadly agreed that core data should stay open, but that products, services, credits, regulation and partnerships must become part of sustaining the infrastructure.
Libby Ellwood, James Macklin, André Zerger ↗
Post-BioDT lessons and next-generation biodiversity digital twins
BioDT delivered pilots and, above all, mutual understanding between modellers and data people; the next generation must find real users and real conservation impact rather than chase the digital twin label.
Claus Weiland, Dimitri, Sharif Islam ↗
Panel discussion: From Mobilizing Data to AI-Ready Knowledge
AI-readiness is purpose-dependent, and the hardest remaining problems are social: trust, attribution, governance and data sovereignty, where ontologies and knowledge graphs offer some control and explainability.
Hilmar Lapp, Robert Guralnick, Tanya Berger-Wolf ↗
Bionomia, Scholia, Wikidata and Zenodo: broadcasting biodiversity data contributions
Linking people, specimens, publications, datasets and collections through Wikidata and associated tools (Bionomia, Scholia, Expeditia, Zenodo) makes biodiversity contributions findable and creditable.
Siobhan Leachman ↗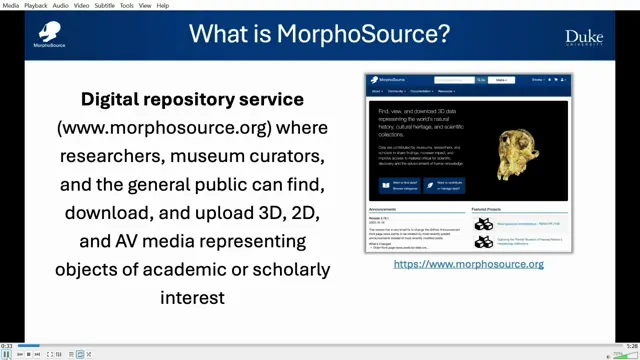
A Network That Is Social: A Community-Based Model and Plan for Sustaining MorphoSource, a Scholarly 3D Data Repository
MorphoSource will sustain open access to 3D data by charging museums, journals, societies and depositors, never downloaders, as NSF funding ends.
Julie Winchester ↗
What is the Role of "AI" in the Centers for Biodiversity Informatics of the Future?
Biodiversity informatics centres are about people. AI raises the importance of standards, storage, openness and distributed risk, and centres should fuel researchers' curiosity rather than be driven by the technology.
Matthew Yoder ↗
Discussion: designing institutional biodiversity knowledge and data science centres
Interoperable institutional knowledge spaces depend less on technology than on people, shared storage and semantics, incentives and governance.
Unidentified session chair, Lars Vogt, Tarek Al Mustafa ↗