
Open Digital Curation Needs: openness, interoperability, provenance
Deborah Paul · Responsible AI, Open Digital Curation, and Round-Tripping for Biodiversity Data
Summaries and key moments are machine-produced. Check the recording for the speaker’s exact words.
The short versionOpen digital curation increases transparency, agency and trust and reduces latency, but needs new provenance practices for AI.
What this was about
Deborah (Debbie) Paul, from the team behind TaxonWorks, Catalogue of Life work and Global Names, argued that open digital curation - built on openness, interoperability, provenance and identifiers - empowers wider participation and shortens the path from spotting an error to fixing it. Examples included Bionomia profiles that keep deceased collectors' expertise attributed, an iNaturalist user fixing names directly in the Orthoptera Species File, and TaxonWorks features letting projects search and clone each other's controlled vocabularies linked to ontologies. She welcomed agents (including LLMs) with roles in the Darwin Core Data Package, raised questions about what provenance we must now track for AI use, and asked how shifting openness (API keys, CC0 to CC BY, logins) will affect interoperability.
Why it matters. Frames the symposium's themes and poses concrete open questions for standards around AI provenance and openness.
In the room
- Her team works on TaxonWorks, Catalogue of Life and Global Names; about 25% of Catalogue of Life names reaching the GBIF backbone come from TaxonWorks workbenches.
- Openness, interoperability and provenance all depend on identifiers and TDWG standards; most interoperability pieces now exist.
- Bionomia lets expertise of people no longer active continue to be credited; an early-career researcher's Zenodo dataset updated via the Bionomia API has been downloaded over 1,000 times.
- Human-mediated round-tripping: an iNaturalist user reports Orthoptera name issues directly in the Orthoptera Species File GitHub repo, shortening the time to fix.
- TaxonWorks lets projects create controlled vocabulary terms linked to ontology URIs (e.g. 'petiole' in plants vs insects), and search and clone other projects' terms.
- Darwin Core Data Package agents can be LLMs; agents need identifiers and roles, which aligns with TaxonWorks' person-role model.
- Journal policies (e.g. Pensoft) ask authors to state AI use in methods and forbid reviewers putting unpublished manuscripts through AI.
Notable moments
Transcript
Automatically generated captions can contain mistakes, especially in names and technical terms. Times are relative to the room recording.
Read the transcript ↓
Related talks.
Open Digital Curation and Round-Tripping Biodiversity Data Enhancements Across Collection Infrastructures: Six Years and 50 Million Links in Bionomia
Round-tripping is much harder than expected, and data managers must fully populate identifiedBy so taxonomists' expertise is credited.
Aligning An Evolving Global Data Model To Software With Global Ambitions: GBIF x TaxonWorks
TaxonWorks and DwC-DP have converged conceptually, but exchange between rich models will always be lossy, so mappings should be recorded explicitly.
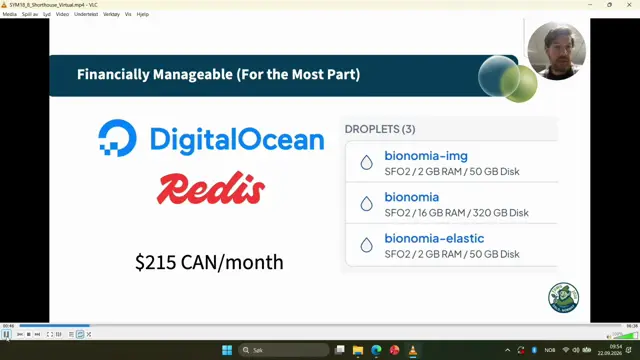
Resilient Attribution Infrastructures for Biodiversity Science: Archiving and Risk Mitigation in Bionomia
Small niche infrastructures can be resilient by planning for their own end: keep things simple and push versioned data and reusable code outward.