
Biodiversity literature as FAIR and AI-ready data by design (and how to get there)
Chris Le Coquet · Planning the Libroscope: creating research ready biodiversity from scientific publications
Summaries and key moments are machine-produced. Check the recording for the speaker’s exact words.
The short versionDon't just liberate biodiversity literature, publish it liberated.
What this was about
Chris Le Coquet argued that the next step is not liberating more literature but changing how it is published. Rather than creating PDFs that must later be mined, XML-first single-source workflows (e.g. MitoTaxa, annotated in JATS TaxPub via GoldenGate) capture structure, references, semantic markup and persistent identifiers during production. Shared standards provide a common grammar, PIDs make entities unambiguous, and together they make publications FAIR by design, part of the Libroscope network and genuinely AI-ready.
Why it matters. Stopping the creation of new PDF backlog would free liberation effort for legacy literature and give AI trustworthy, structured inputs.
In the room
- Publications are infrastructure through which knowledge is validated, connected and reused.
- Plazi has liberated more than one million treatments from legacy literature; the question is whether this should remain the way we publish.
- In XML-first workflows, machine-readable structure exists from the start and many outputs derive from one source.
- References become structured objects that can be matched and resolved, preserving relationships for knowledge graphs.
- Semantic markup turns material citations into explicit entities and relationships.
- Machine-readable is not interoperable: standards (JATS TaxPub, Darwin Core, ontologies) give a common grammar and PIDs give identity.
- AI readiness is a consequence of good semantic publishing; the challenge now is scale and community convergence.
Notable moments
Transcript
Automatically generated captions can contain mistakes, especially in names and technical terms. Times are relative to the room recording.
Read the transcript ↓
Related talks.
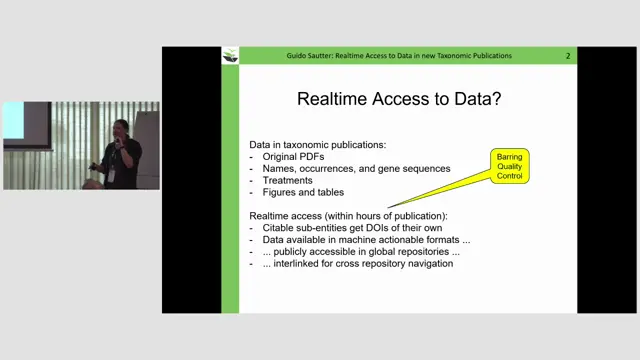
Realtime Access to Data in new Taxonomic Publications
Plazi can deliver interlinked, machine-actionable data from new taxonomic papers within hours, and XML-first publishing removes most of the costly effort.
The future is the future - thought about access to data in publications
Liberating data from literature works, but the future lies in use-case-driven, digital-first publishing that also targets the undescribed majority of species.
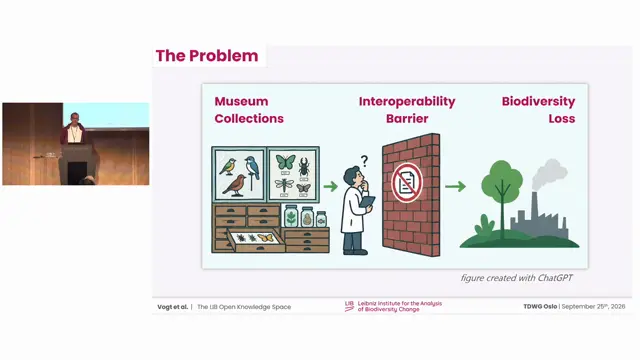
The LIB Open Knowledge Space: A semantic architecture for FAIR, CLEAR, and AI-ready biodiversity knowledge
Knowledge can enter the LIB Open Knowledge Space as natural language immediately and be formalised step by step, so content becomes FAIR, CLEAR and AI-ready incrementally.