
The LIB Open Knowledge Space: A semantic architecture for FAIR, CLEAR, and AI-ready biodiversity knowledge
Lars Vogt · Designing Institutional Knowledge Data Science Centres for Biodiversity
Summaries and key moments are machine-produced. Check the recording for the speaker’s exact words.
The short versionKnowledge can enter the LIB Open Knowledge Space as natural language immediately and be formalised step by step, so content becomes FAIR, CLEAR and AI-ready incrementally.
What this was about
Vogt presented the planned LIB Open Knowledge Space, the core infrastructure of LIB's new Centre for Biodiversity Knowledge Science. He argued that FAIR efforts often make only containers (metadata) FAIR rather than content. The architecture combines the Semantic Units framework, in which each humanly meaningful statement is an identifiable, versioned resource with metadata and vector embeddings, with a 'semantic ladder' of progressive formalisation. The ladder runs from raw text snippets through entity-linked snippets and Rosetta statements to OWL or higher-logic models, and the running example was a beetle observed feeding on carrion.
Why it matters. The approach lowers the entry barrier for semantic knowledge graphs while keeping a route to full formal semantics, and it offers a model for institutional knowledge centres built on natural history collections.
In the room
- FAIRness is a continuum, not a Boolean; many projects build 'FAIR containers, not FAIR content'.
- Semantic units: every semantically meaningful piece of content gets its own identifier, instantiates a type, and carries provenance and technical metadata, source reference, extraction method and a vector embedding.
- Ladder level 1: a text snippet linked via a data property, with no formalisation cost. Level 2: entity recognition and linking to Wikidata or ontology terms for basic semantic search.
- Rosetta statements use linguistic syntax-tree positions and semantic roles to create formalised, still natural-language statement types, represented in RDF by n-ary reification. They can be queried with SPARQL, validated with SHACL, and rendered as dynamic labels.
- Higher levels: OWL-based models reached via schema crosswalks from Rosetta schemas. The approach is technology-agnostic (RDF/OWL, property graph or relational).
- LIBTellMe, a RAG chatbot over LIB documents, will let users push relevant answers into the space as text snippet units. Diversity Workbench collection data will be imported at higher formalisation levels.
- A vector layer runs alongside the ladder; each rank adds FAIRness and AI-readiness, and content is only pushed up when a use case needs it.
Notable moments
Transcript
Automatically generated captions can contain mistakes, especially in names and technical terms. Times are relative to the room recording.
Read the transcript ↓
Related talks.
BHL and the Planetary Knowledge Base: Structuring Biodiversity Literature for the Next Generation
NHM is re-OCRing all of BHL with modern models and extracting entities into a knowledge graph, with confidence gating to protect BHL data quality.
Using Large Language Models to enhance biodiversity knowledge extraction: From taxonomic treatments to graph-based knowledge systems
Taxonomic treatments hold underused habitat knowledge that LLMs and a provenance-preserving knowledge graph can structure and link to ecoregions, helping map data-poor species.
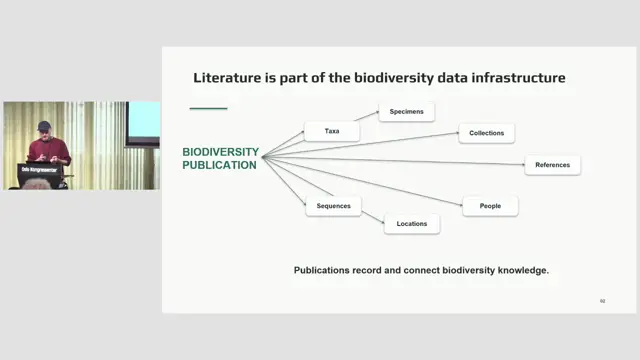
Biodiversity literature as FAIR and AI-ready data by design (and how to get there)
Don't just liberate biodiversity literature, publish it liberated.