
Realtime Access to Data in new Taxonomic Publications
Guido Sautter · Planning the Libroscope: creating research ready biodiversity from scientific publications
Summaries and key moments are machine-produced. Check the recording for the speaker’s exact words.
The short versionPlazi can deliver interlinked, machine-actionable data from new taxonomic papers within hours, and XML-first publishing removes most of the costly effort.
What this was about
Guido Sautter detailed Plazi's pipeline turning new taxonomic publications into FAIR data within hours. XML from Pensoft (TaxPub via RSS) needs structural normalisation, while PDFs must be obtained from publishers and decoded, with document structure detection being the main quality-control cost. The workflow tags names, citations, material citations and treatment sections, links names to Catalogue of Life and accessions to ENA, and exports to Zenodo, GBIF, ChecklistBank, Biodiversity PMC, RefBank, OpenBiodiv and others, receiving identifiers back to interlink everything.
Why it matters. It explains concretely where effort goes in literature data liberation, supporting the argument for semantic-first publishing.
In the room
- 'Real-time' means same day or within a couple of hours, barring quality control.
- Data in publications: the PDF, named entities (names, occurrences, specimens, sequences), treatments, figures and tables.
- Figures and tables receive DOIs in Zenodo so they can be cited directly.
- Pensoft XML (TaxPub/JATS) is pulled via RSS but needs paragraph-nesting normalisation.
- PDF intake depends on publishers (MNHN journals upload directly); structure detection dominates QC effort.
- Names are linked to Catalogue of Life, new species to ZooBank; ZooBank names without treatments get 'treatment stubs'.
- Exports return identifiers (GBIF dataset keys, Zenodo DOIs) that are disseminated back across repositories.
Notable moments
Transcript
Automatically generated captions can contain mistakes, especially in names and technical terms. Times are relative to the room recording.
Read the transcript ↓
Related talks.
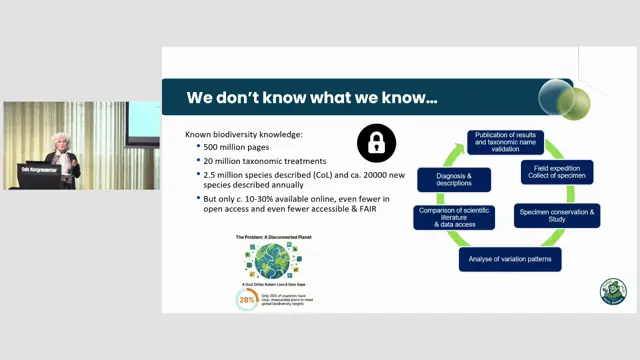
Building digital-native species: Transitioning from PDF liberation to semantic-by-design publishing
Keeping data linked and structured from specimen to publication yields FAIR, trusted data on the day of publication.
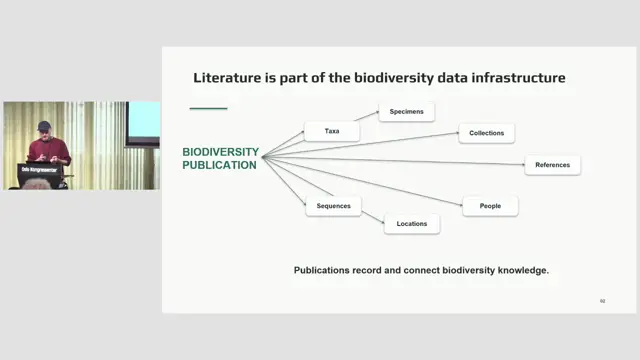
Biodiversity literature as FAIR and AI-ready data by design (and how to get there)
Don't just liberate biodiversity literature, publish it liberated.
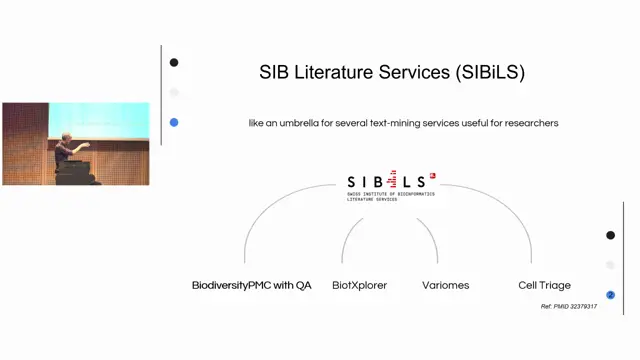
How Literature Services can Support & Benefit from Biodiversity Publication and Data Standards?
Standards-based concept annotation of biodiversity literature enables focused, evidence-grounded question answering that is more precise than general chatbots.