
Digital curation across the biodiversity data lifecycle, at the node level (SiB Colombia), aggregator level (GBIF) and how to incorporate user feedback
Esteban Marentes Herrera · Responsible AI, Open Digital Curation, and Round-Tripping for Biodiversity Data
Summaries and key moments are machine-produced. Check the recording for the speaker’s exact words.
The short versionCuration feedback works at every stage of the data lifecycle, and about a third or more of reported issues do get fixed; AI is used cautiously to summarise feedback.
What this was about
Esteban Marentes described curation as a circular process with feedback loops at node, aggregator and user levels. At SiB Colombia, every dataset receives human 'acompañamiento' - a semi-automatic review with OpenRefine, the GBIF API and QGIS of metadata and 30-40 Darwin Core elements - before publication. GBIF interprets names and other fields and exposes flags through the Data Validator and annotated downloads. Of about 700 helpdesk messages in three months, 45% of taxonomy issues and about 37% of data-content issues were fixed; an LLM in GitHub Actions summarises taxonomic feedback into JSON (edited by staff about 70% of the time) and a deterministic script checks the Catalogue of Life extended release to close resolved issues.
Why it matters. Quantifies how user feedback flows back to data and shows a careful, human-reviewed use of LLMs in aggregator operations.
In the room
- Data flow: publisher -> node/data manager feedback -> GBIF feedback -> users providing feedback to GBIF, nodes or publishers; nodes differ in approach.
- SiB Colombia reviews every dataset before GBIF publication using OpenRefine, the GBIF API and QGIS, recording fixes and required changes in an Excel report; publication only after fixes.
- GBIF interprets names, elevations, dates and vocabularies and raises flags (fuzzy taxon match, invalid date, invalid coordinates).
- Publishers can use the GBIF Data Validator; users can see issues in annotated downloads and dataset-level summaries.
- Roughly 700 helpdesk messages in Q1: mostly general help, then IPT, then taxonomy; 46 about data content.
- About 45% of taxonomy feedback fixed, largely via the Catalogue of Life extended release; about 37% of data content issues fixed by publishers.
- An OpenAI LLM in GitHub Actions summarises taxonomic feedback into categorised JSON; staff edit about 70% of outputs; a deterministic script re-checks each issue against the latest CoL extended release monthly.
Notable moments
Transcript
Automatically generated captions can contain mistakes, especially in names and technical terms. Times are relative to the room recording.
Read the transcript ↓
Related talks.
Reconsidering the original vision for a global biodiversity information facility
GBIF achieved its 1999 vision only partially and through a network of collaborating infrastructures; the community must decide whether that is enough and articulate the next vision.
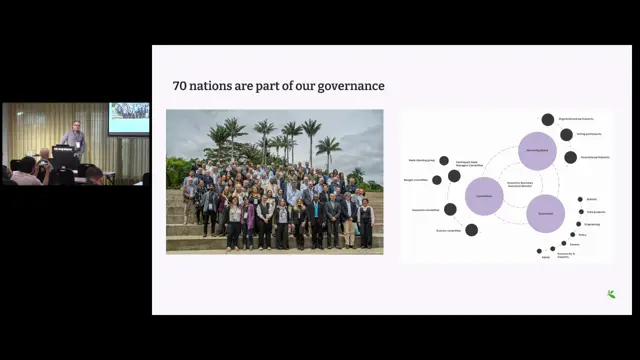
GBIF after 25 years
GBIF sustains itself by leveraging stable national contributions into additional funding and by embedding itself in the biodiversity policy and funding architecture.
Modernizing Brazil's taxonomic backbone: how ChecklistBank supports biodiversity and genetic heritage systems
ChecklistBank lets a small national node assemble one consistent taxonomic backbone for legal, portal and permitting systems.