
An Introduction to the Biodiversity Data Quality Standard (BDQ)
Lee Belbin · Data Quality: From Standard to Practice
Summaries and key moments are machine-produced. Check the recording for the speaker’s exact words.
The short versionBDQ provides 110 standard, use-case-linked tests so that data quality can be assessed consistently from collection to aggregation.
What this was about
Lee Belbin introduces the proposed TDWG Biodiversity Data Quality (BDQ) standard: a unified, transparent framework of 110 core single-record tests derived from reviewing over 500 tests run by aggregators. Tests take information elements (Darwin Core as example, but data-structure agnostic), parameters and source authorities, and are of four types (validations, amendments, issues, measures) described in seven vocabularies and one ontology. He stresses that data quality cannot be defined without a use case, that tests should be applied from the point of collection onward, and mentions using Gemini Notebooks with the ~800 pages of documentation to prepare the slides.
Why it matters. A shared data quality test suite would let publishers, aggregators and users assess fitness for use consistently instead of each running idiosyncratic checks.
In the room
- Work started from the idea at Woods Hole in 2010 and was convened from 2014; it took far longer than the expected year and a half.
- Over 500 tests from aggregators (ALA, GBIF, iDigBio, BISON, etc.) were reviewed to build a single framework.
- Output: 110 core single-record tests and four use cases; adding a test requires justifying it by a use case (tutorial and BDQUC vocabulary).
- Tests use information elements, parameters and source authorities (e.g. ISO 3166) and are independent of Darwin Core, ABCD or data packages.
- Four test types: validation (e.g. country found), amendment (e.g. month standardized, not to be applied without consideration), issue (e.g. annotation not empty, some tests aspirational) and measure.
- Seven vocabularies and one ontology (BDQ FFDQ) underpin the standard.
- Cradle-to-grave approach: ideally apply tests at collection (e.g. in Specify or field apps) as well as by aggregators.
Notable moments
Transcript
Automatically generated captions can contain mistakes, especially in names and technical terms. Times are relative to the room recording.
Read the transcript ↓
Related talks.
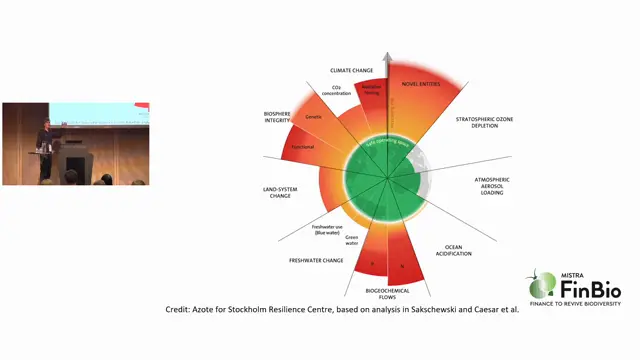
Data Quality in Focus: Bridging the Biodiversity Data Gap for Sustainable Finance
Biodiversity assessments for finance need local data; a tiered data-quality hierarchy like carbon accounting could make them credible.
Address from the TDWG Chair: highlights of the year and TDWG at a crossroads
TDWG has had a productive year, but a growing, more diverse community and the rise of AI put it at a crossroads that needs more volunteers, better documentation and more sustainable maintenance and funding.
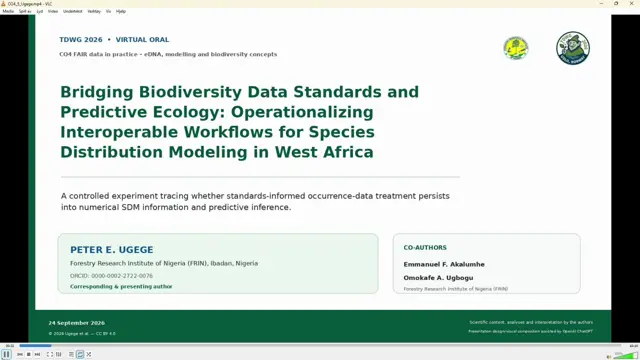
Bridging Biodiversity Data Standards and Predictive Ecology: Operationalizing Interoperable Workflows for Species Distribution Modeling in West Africa
Standards change what enters a modelling pipeline, but workflow design determines whether that difference survives and validation design determines what claims can be made.