
Bridging Biodiversity Data Standards and Predictive Ecology: Operationalizing Interoperable Workflows for Species Distribution Modeling in West Africa
Peter Ugege · FAIR data in practice - eDNA, modelling and biodiversity concepts
Summaries and key moments are machine-produced. Check the recording for the speaker’s exact words.
The short versionStandards change what enters a modelling pipeline, but workflow design determines whether that difference survives and validation design determines what claims can be made.
What this was about
Peter Ugege reported a controlled experiment asking whether standards-informed processing of occurrence records changes species distribution model outcomes for six West African timber species. Starting from 46,941 records, the standards pathway removed 106 records (placeholders, duplicates, a fuzzy and absent records), but after domain restriction and spatial deduplication both pathways converged on identical 36,407 presence units, so no pathway-specific predictive effect was identifiable. Geographic cross-validation gave ROC-AUC of about 0.66-0.75, far below random cross-validation (~0.99), showing random validation overstates transferability.
Why it matters. It gives a rigorous, reproducible test of the downstream effect of data standards on SDMs and a clear warning about optimistic random cross-validation.
In the room
- Three levels of effect were distinguished: record representation, numerical SDM information and predictive inference.
- Pathway A (minimal processing) kept 46,941 records; pathway B (standards-informed fitness-for-use rules) kept 46,835, a 0.23% difference.
- Within the West African domain the difference fell to 70 records, concentrated in three species and 16 locations, all already represented in pathway B.
- After common spatial deduplication both yielded 36,407 presence units and the same 96,407-row modelling matrix.
- Models: logistic regression, random forest and histogram gradient boosting, with strict geographic cross-validation.
- Random CV mean ROC-AUC ~0.99 vs ~0.70 under geographic hold-out (mean difference 0.28).
- No species was best on every robustness dimension, so no composite score was used.
Notable moments
Transcript
Automatically generated captions can contain mistakes, especially in names and technical terms. Times are relative to the room recording.
Read the transcript ↓
Related talks.
An Introduction to the Biodiversity Data Quality Standard (BDQ)
BDQ provides 110 standard, use-case-linked tests so that data quality can be assessed consistently from collection to aggregation.
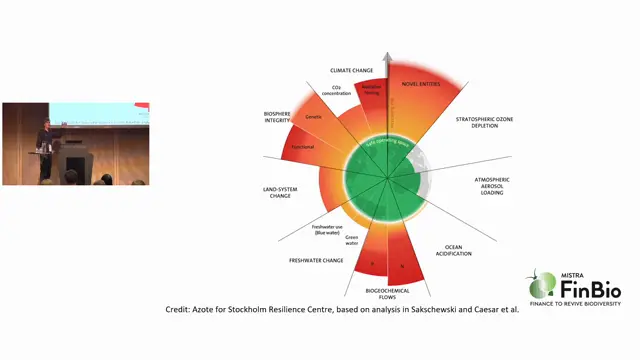
Data Quality in Focus: Bridging the Biodiversity Data Gap for Sustainable Finance
Biodiversity assessments for finance need local data; a tiered data-quality hierarchy like carbon accounting could make them credible.
Reporting structure and sampling-bias correction in citizen-science bird data across Asian cities
Abundant citizen-science records do not guarantee inference support; reporting structure can distort richness hotspots and urban-biodiversity relationships unless it is diagnosed and controlled.