
From Buzzwords to Blueprints: What It Really Takes to Operationalise Biodiversity Digital Twins
Sharif Islam · Operationalizing Biodiversity Digital Twins within Data Space Ecosystems
Summaries and key moments are machine-produced. Check the recording for the speaker’s exact words.
The short versionUse buzzwords to get funded, then break them down into concrete blueprints: metadata, catalogues, governance and stewardship in the middle layer.
What this was about
Sharif Islam used the Gartner hype cycle to argue that buzzwords like 'digital twin' and 'data space' help win funding but do not help once projects start. His blueprint places the real work in a middle 'control plane' of context, discovery, governance and contracts between fragmented data sources and the consumers (media, funders, policymakers) that buzzwords address. Drawing on BioDT, he said FAIR digital twins boil down to metadata profiles and cross-domain mappings; for BMD he described a STAC-based catalogue with GeoParquet and cloud-native formats so users can query and fetch only the slices they need, including the cubes from the cubing engine.
Why it matters. It gives a pragmatic framing for turning digital twin and data space funding language into implementable components, and names governance and stewardship as work that must be resourced.
In the room
- Digital twin peaked on Gartner's 2018 hype cycle; by 2025 it had been replaced by agents and physical AI, while BioDT (2022) and DTO-BioFlow (2023) were funded on the term.
- Buzzwords help proposals but when real work starts teams must still define what a digital twin or data space actually is.
- The blueprint: fragmented sources on one side, consumers on the other, and a middle layer of context, discovery, governance and contracts that can be centralised or federated.
- BioDT experience: FAIR for digital twins boils down to metadata; human communication issues (e.g. 'model calibration' vs 'model training') required mandatory metadata profiles (model version, datasets, inputs/outputs) and mappings.
- In BMD, heterogeneous inputs (Natura 2000 boundaries, EEA species checklists, camera trap and eDNA surveys) are brought together via the cubing engine and a centralised metadata catalogue, plus access control for restricted species.
- STAC is a simple static-JSON metadata catalogue with a common API and search; with GeoParquet it can index many S3 objects and supports geospatial and metadata queries.
- Cloud-native formats let users take only the slice they need instead of downloading huge CSV files; cubes can likewise be sliced for different audiences.
Notable moments
Transcript
Automatically generated captions can contain mistakes, especially in names and technical terms. Times are relative to the room recording.
Read the transcript ↓
Related talks.
Post-BioDT lessons and next-generation biodiversity digital twins
BioDT delivered pilots and, above all, mutual understanding between modellers and data people; the next generation must find real users and real conservation impact rather than chase the digital twin label.
Operationalising biodiversity DT ecosystems through assessment-driven service mapping and reusable tools and workflow integration
A simple, purpose-first assessment that maps a team's needs and capabilities to an inventory of existing tools helps digital twin projects reuse rather than rebuild.
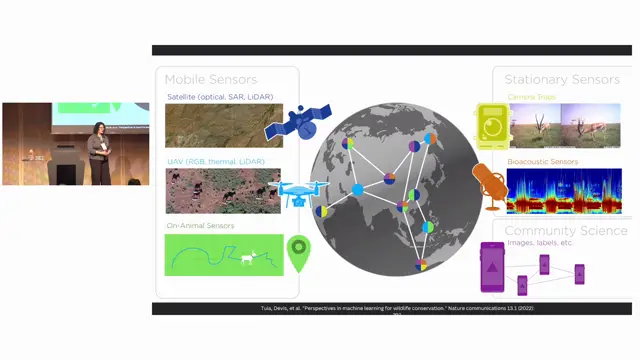
Digital Twins as System-Optimization Tools: Provisioning Edge and Cloud Infrastructure for Biodiversity Monitoring at Scale
Digital twins should close the sim-to-real loop for the sensor systems too, letting teams plan where and how to deploy multimodal monitoring before going into the field.