
Automated data transcription and Darwin Core field itemization from insect specimen labels using machine learning
Torsten Dikow · Large Language Models for Biodiversity Data Discovery, Integration, and Curation. Part A: AI- enabled knowledge creation and extraction
Summaries and key moments are machine-produced. Check the recording for the speaker’s exact words.
The short versionLabellum goes beyond label OCR to itemise insect-label text into Darwin Core fields, with high accuracy for most fields but problems with catalogue numbers.
What this was about
Torsten Dikow described Labellum, built with University of Maryland students, which transcribes pinned-insect labels from the NMNH conveyor digitisation project and itemises the text into Darwin Core fields. The three-step pipeline uses YOLO to extract labels (about 95%), a Gemini/Gemma 3 12B model to transcribe (about 82%), and Gemini to sort text into Darwin Core 'buckets' using prompts with controlled vocabularies and field definitions. On 100 labels generated from his research database, country and verbatim date were 98-99% correct and genus/epithet errors were 7-10%, but catalogue numbers (USNMENT) were often missed or misread.
Why it matters. At up to 1,500 specimens a day from a conveyor, human transcription is a bottleneck; automated Darwin Core itemisation could speed up data mobilisation to GBIF for many collections.
In the room
- NMNH is digitising about 360,000 of its 2.4 million pinned pollinators (bees, beetles, butterflies, flies) since June 2025, using a Picturae conveyor at up to 1,500 specimens per day.
- Current transcription is by an external vendor (Alembo) with no interpretation (e.g. 'CA' is not expanded to California).
- Published tools extract label text as a long string; Labellum's goal is Darwin Core itemisation.
- Step 1: YOLO extracts individual labels (initial ~95% accuracy). Step 2: text transcription per label with a lightweight Gemini / Gemma 3 12B (~82%). Step 3: 'bucket extraction' into Darwin Core fields with Gemini.
- Prompts give project context, controlled vocabularies for countries, Darwin Core field definitions and an output format.
- Evaluation on 100 labels with known database records: country 99%, verbatim date 98%, genus/epithet error rates 7% and 10% (after accounting for labels with no name).
- USNMENT catalogue numbers were missed in 35% of cases and a poorly printed '7' was read as '/' in 6%.
Notable moments
Transcript
Automatically generated captions can contain mistakes, especially in names and technical terms. Times are relative to the room recording.
Read the transcript ↓
Related talks.
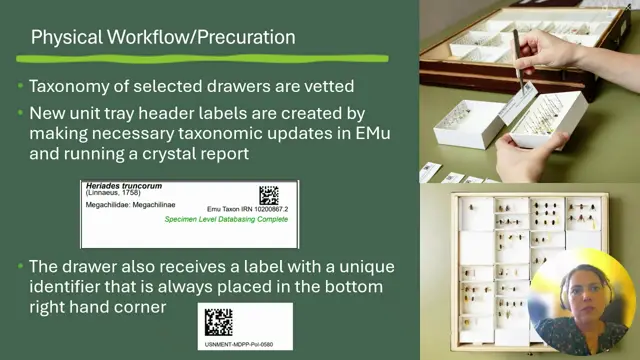
Pinned insect digitization conveyor: image and data transcription workflows
An industrial conveyor workflow with QR-encoded metadata and automated skeletal records makes mass digitisation of pinned insects feasible.
From Collection Drawers to AI - A One-Week Recipe
A useful AI-ready digitisation setup can be built in a week from recycled materials and borrowed cameras.
Closing Gaps in Specimen Metadata: A Collaborative Annotation and Feedback Platform for Natural History Collections
A national collaborative annotation platform with AI-assisted transcription can close metadata gaps across many Taiwanese collections.